Computer Science · Harvard University

Andrew Cheng

I’m a PhD student at Harvard University, advised by Yue Lu.

My research connects machine learning, optimization, and statistics. My recent work focuses on enabling fast decision-making for foundation models on unstructured data.

My earlier work explored Riemannian optimization and high-dimensional learning dynamics. I also developed interpretable models with provable guarantees for large-scale tabular data, applying them to problems in national security and healthcare.

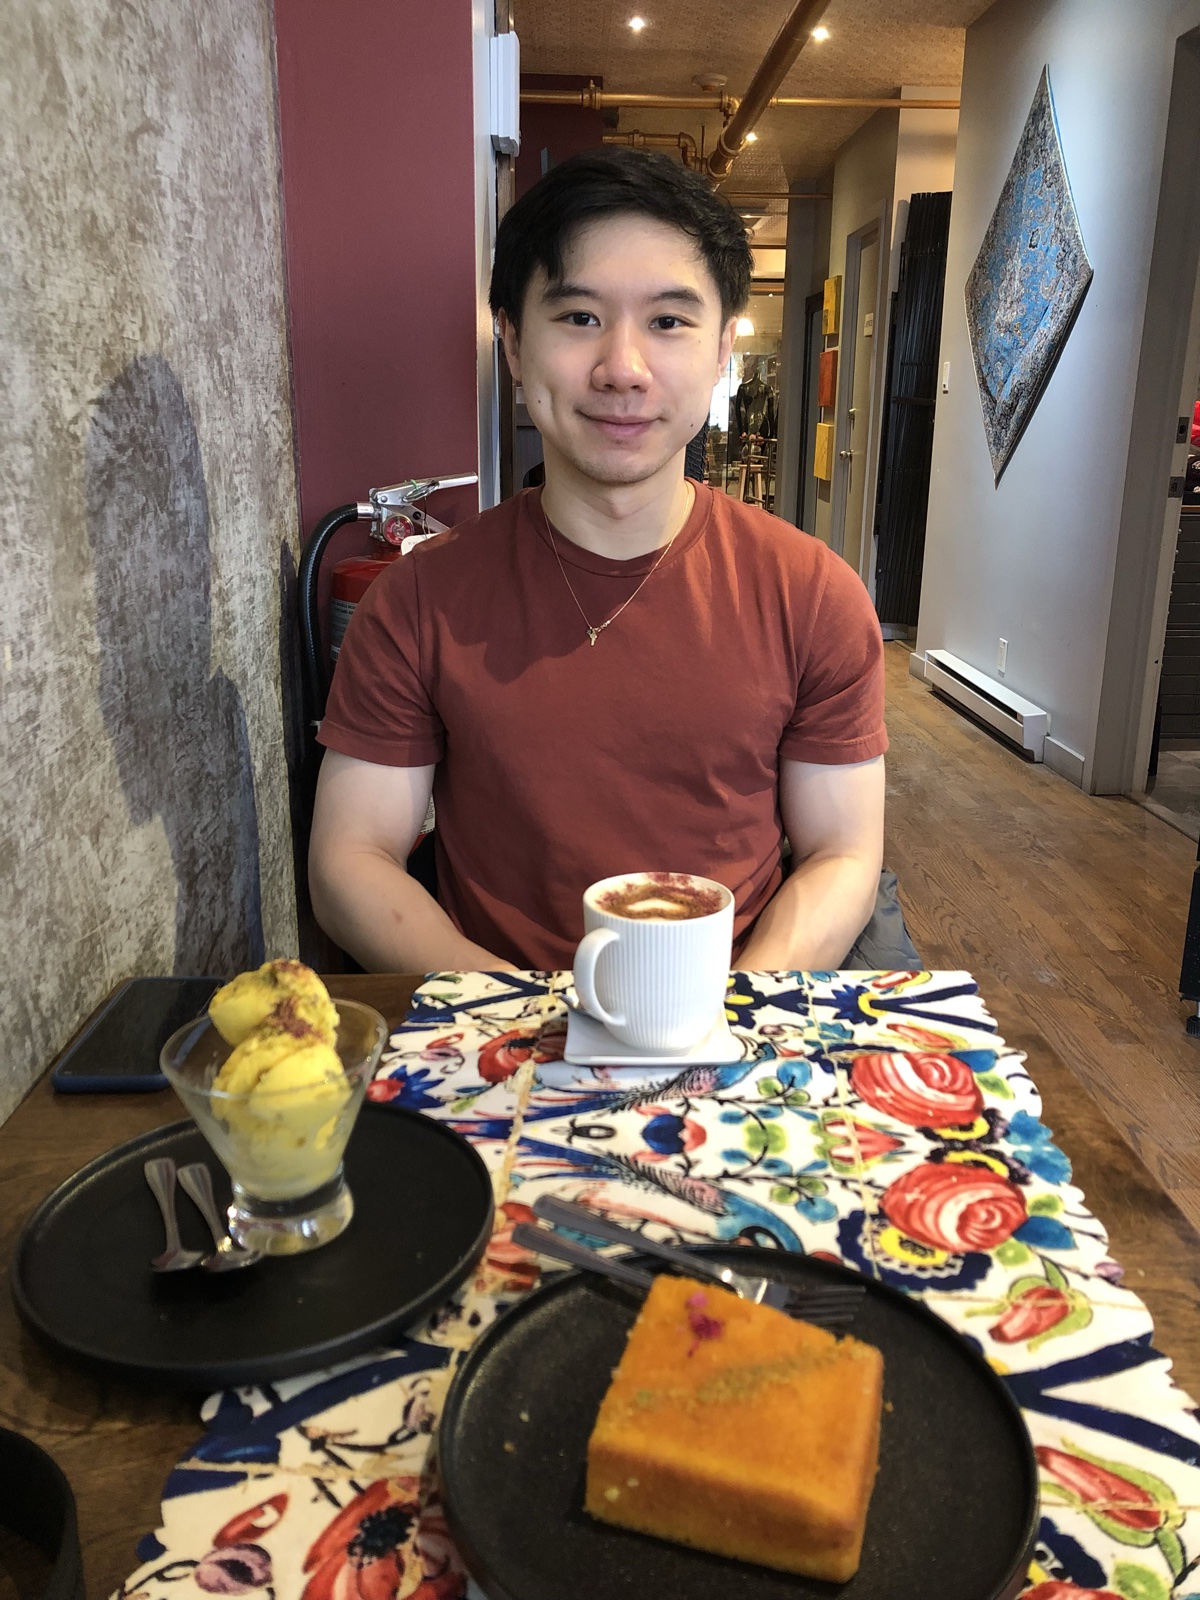
Andrew Cheng seated at a café

Background

McGill University Mila

During my master’s, I was advised by Courtney Paquette and Elliot Paquette. I also completed my bachelor’s in Statistics and Computer Science at McGill.

Research support

My work has been supported in part by the NSERC Postgraduate Scholarship, Harvard’s Dean’s Competitive Fund for Promising Scholarship, NSF, and FQRNT.

Experience

The Voleon Group

· Incoming

Quantitative research intern

Voloridge

Quantitative research

Lawrence Livermore National Laboratory

–

Machine learning for national security problems in energy.

Valence Labs

–

Generative AI models for drug discovery.

Papers & preprints

Research

Google Scholar
Four seeded Gaussian sample spectra at n = 64, 256, 1024, and 4096, with p/n fixed at one half, compared with a stationary Marchenko–Pastur law. Rust stems mark the two largest sample eigenvalues; faint guides mark their asymptotic limits. This is an illustrative model.
Original SGD-with-momentum training-loss bands from Figure 1, on a logarithmic scale. Bands for n = 64, 256, 1024, and 4096 at fixed d/n are shown around the Volterra prediction.

n = 4096 · d/n fixed

High-dimensional learning dynamics
Illustration of gradient descent following a curved valley to its global minimum.
Manifold optimization
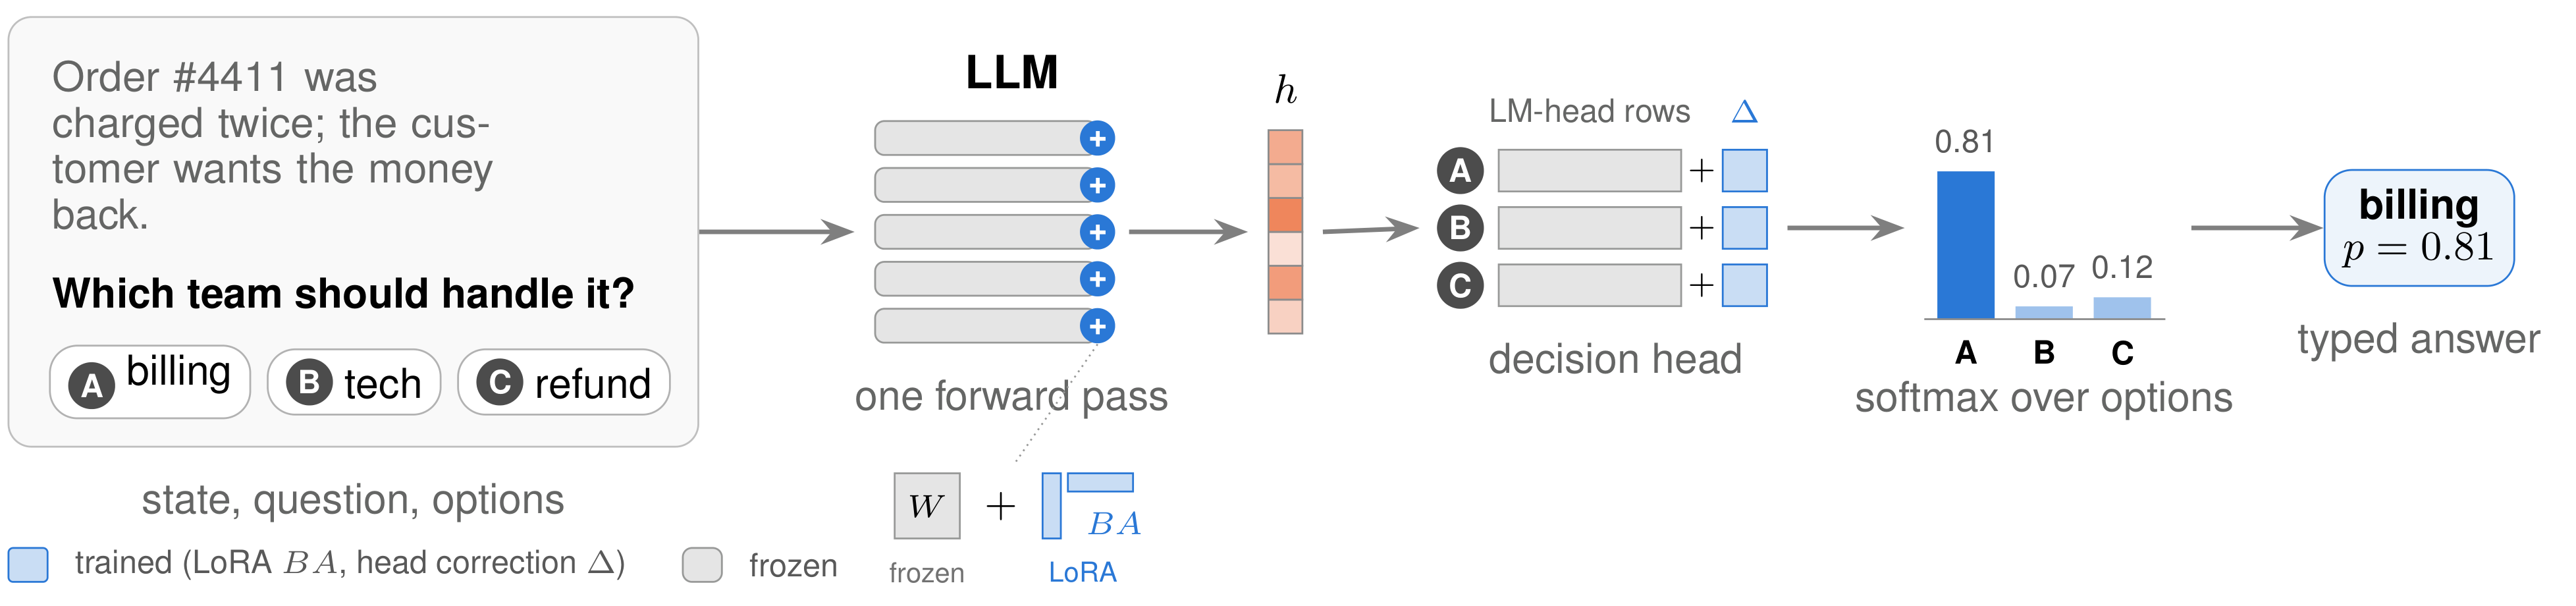
Schematic of tokens passing through model representations and a neural network to a decision.
Fast Decision-Making

A decision request becomes probabilities over its options in one forward pass.

Scroll across the diagram, or tap to enlarge.

Figure 1 · source paper

Preprint

Releasing the Inner Jev: A Simple Recipe for Open Decision Models

Jonathan Geuter*, Andrew Cheng*, David Alvarez-Melis * Equal contribution

We show how open language models can make probabilistic decisions in a single forward pass, without generating text. We study a simple fine-tuning recipe and release models, serving code, and the OpenDecisions benchmark.
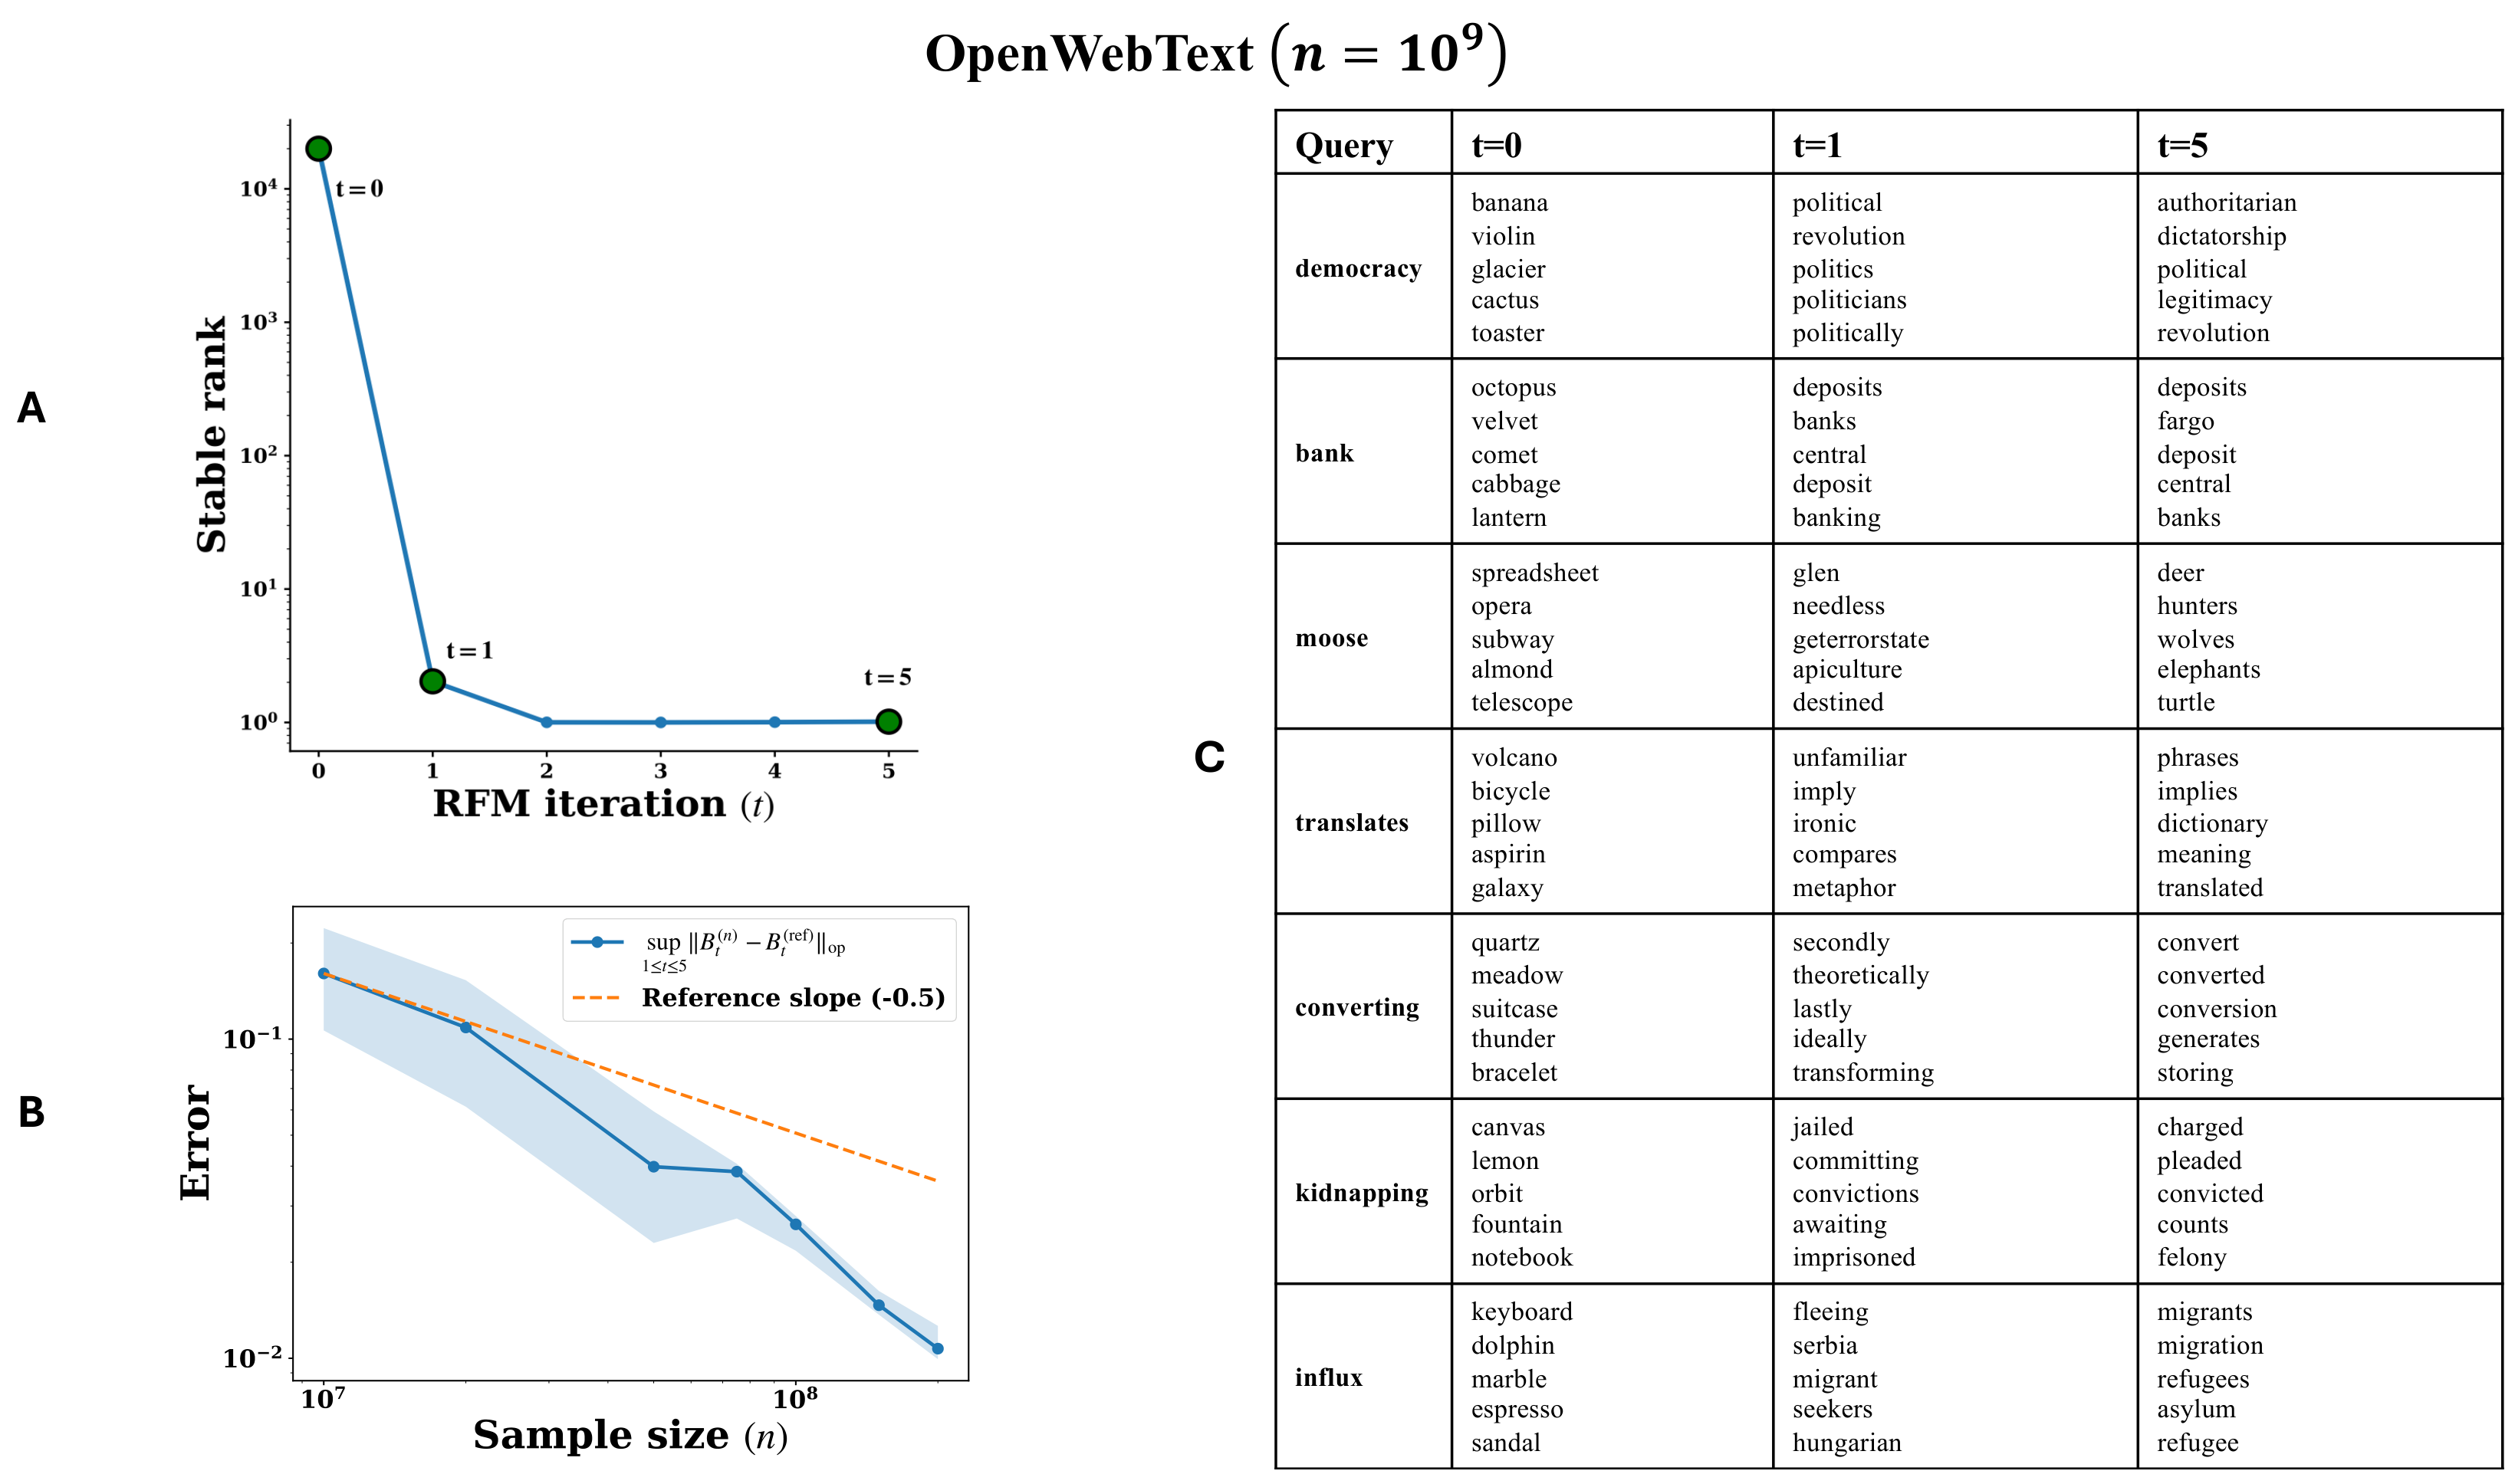
OpenWebText 10⁹ training examples

Full Figure 1
Original panels A and B: stable rank of the floor-subtracted feature matrix versus iteration, and maximum operator-norm discrepancy over iterations 1 through 5 relative to a billion-example reference trajectory versus sample size.

After 5 updates

QuerySelected words
democracyauthoritarian, dictatorship, political, legitimacy, revolution
bankdeposits, fargo, deposit, central, banks
moosedeer, hunters, wolves, elephants, turtle
translatesphrases, implies, dictionary, meaning, translated
convertingconvert, converted, conversion, generates, storing
kidnappingcharged, pleaded, convicted, counts, felony
influxmigrants, migration, refugees, asylum, refugee

Selected cosine neighbors from the learned embedding at t = 5.

Original plots and word lists from Figure 1. Stable rank measures spectral concentration; trajectory error is relative to a 10⁹-example reference.

Figure 1 · source paper

Preprint

Exact Dynamics and Finite-Sample Trajectory Recovery of Linear Recursive Feature Machines

Andrew Cheng, Bobak T. Kiani, Yue M. Lu, Adityanarayanan Radhakrishnan

We characterize how an iterative method alternating ridge regression with average gradient outer product (AGOP) updates learns task-relevant features for multi-output regression. We explain how these features evolve and how much data is needed to reliably recover their learning trajectory.

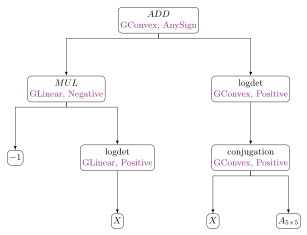
Original expression tree showing symbolic curvature verification, from matrix inputs and atomic operations to a geodesically convex expression.

An expression tree certifying geodesic convexity through composition rules.

Figure 2 · source paper

Mathematical Programming Computation

Disciplined Geodesically Convex Programming: A Symbolic Framework for Verifying Geodesic Convexity

Andrew N. Cheng, Vaibhav Dixit, Melanie Weber

A symbolic framework for checking geodesic convexity on Hadamard manifolds. We identify composition rules and matrix-valued building blocks, and implement automated verification in the Julia package SymbolicAnalysis.jl.

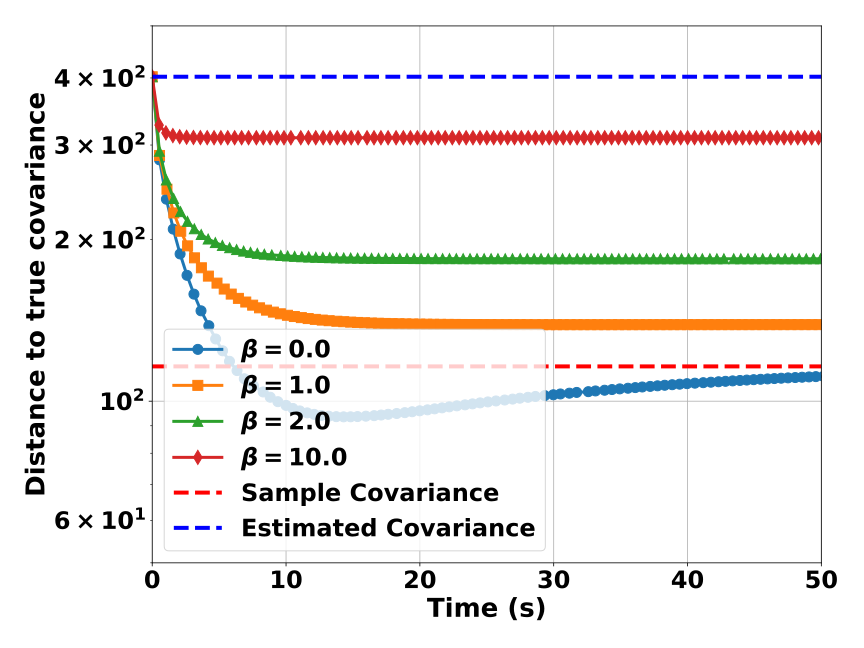
Original Gaussian optimistic-likelihood plot for n = 100 and d = 30, comparing four regularization strengths. Distance to the true covariance is plotted against time.

Gaussian optimistic likelihood with side information, n = 100 and d = 30. Larger β pulls toward the supplied estimate, which need not be the true covariance.

Figure 7 · source paper

IMA Journal of Numerical Analysis

Structured regularization for constrained optimization on the SPD manifold

Andrew Cheng, Melanie Weber

We design regularizers from symmetric gauge functions to handle constraints on positive definite matrices. These regularizers can preserve convexity or difference-of-convex structure, enabling efficient unconstrained optimization on the manifold.

Original SGD-with-momentum learning-dynamics panel, with 90% bands for n = 64, 256, 1024, and 4096 and a deterministic Volterra prediction.
Expand

SGD + momentum: published 90% bands for n = 64, 256, 1024, and 4096 around the deterministic Volterra prediction.

Figure 1 · source paper

NeurIPS OPT Workshop

High Dimensional First Order Mini-Batch Algorithms on Quadratic Problems

Andrew Cheng, Kiwon Lee, Courtney Paquette

We characterize high-dimensional mini-batch learning dynamics for regularized least squares. A deterministic discrete Volterra equation describes quadratic statistics of SGD, stochastic Nesterov, and momentum methods.

Technical details

Under the assumptions in the paper, quadratic statistics \( \mathcal{R}: \mathbb{R}^d \to \mathbb{R} \), including training loss and excess risk, concentrate around deterministic predictions as sample size and dimension grow. The analysis concerns \( \ell_2 \)-regularized least-squares problems.

NeurIPS

Trajectory of Mini-Batch Momentum: Batch Size Saturation and Convergence in High Dimensions

Kiwon Lee, Andrew Cheng, Elliot Paquette, Courtney Paquette

We describe how batch size controls momentum dynamics on high-dimensional least-squares problems. An implicit conditioning ratio identifies when mini-batch momentum can match the accelerated convergence rate of full-batch momentum.

Expand
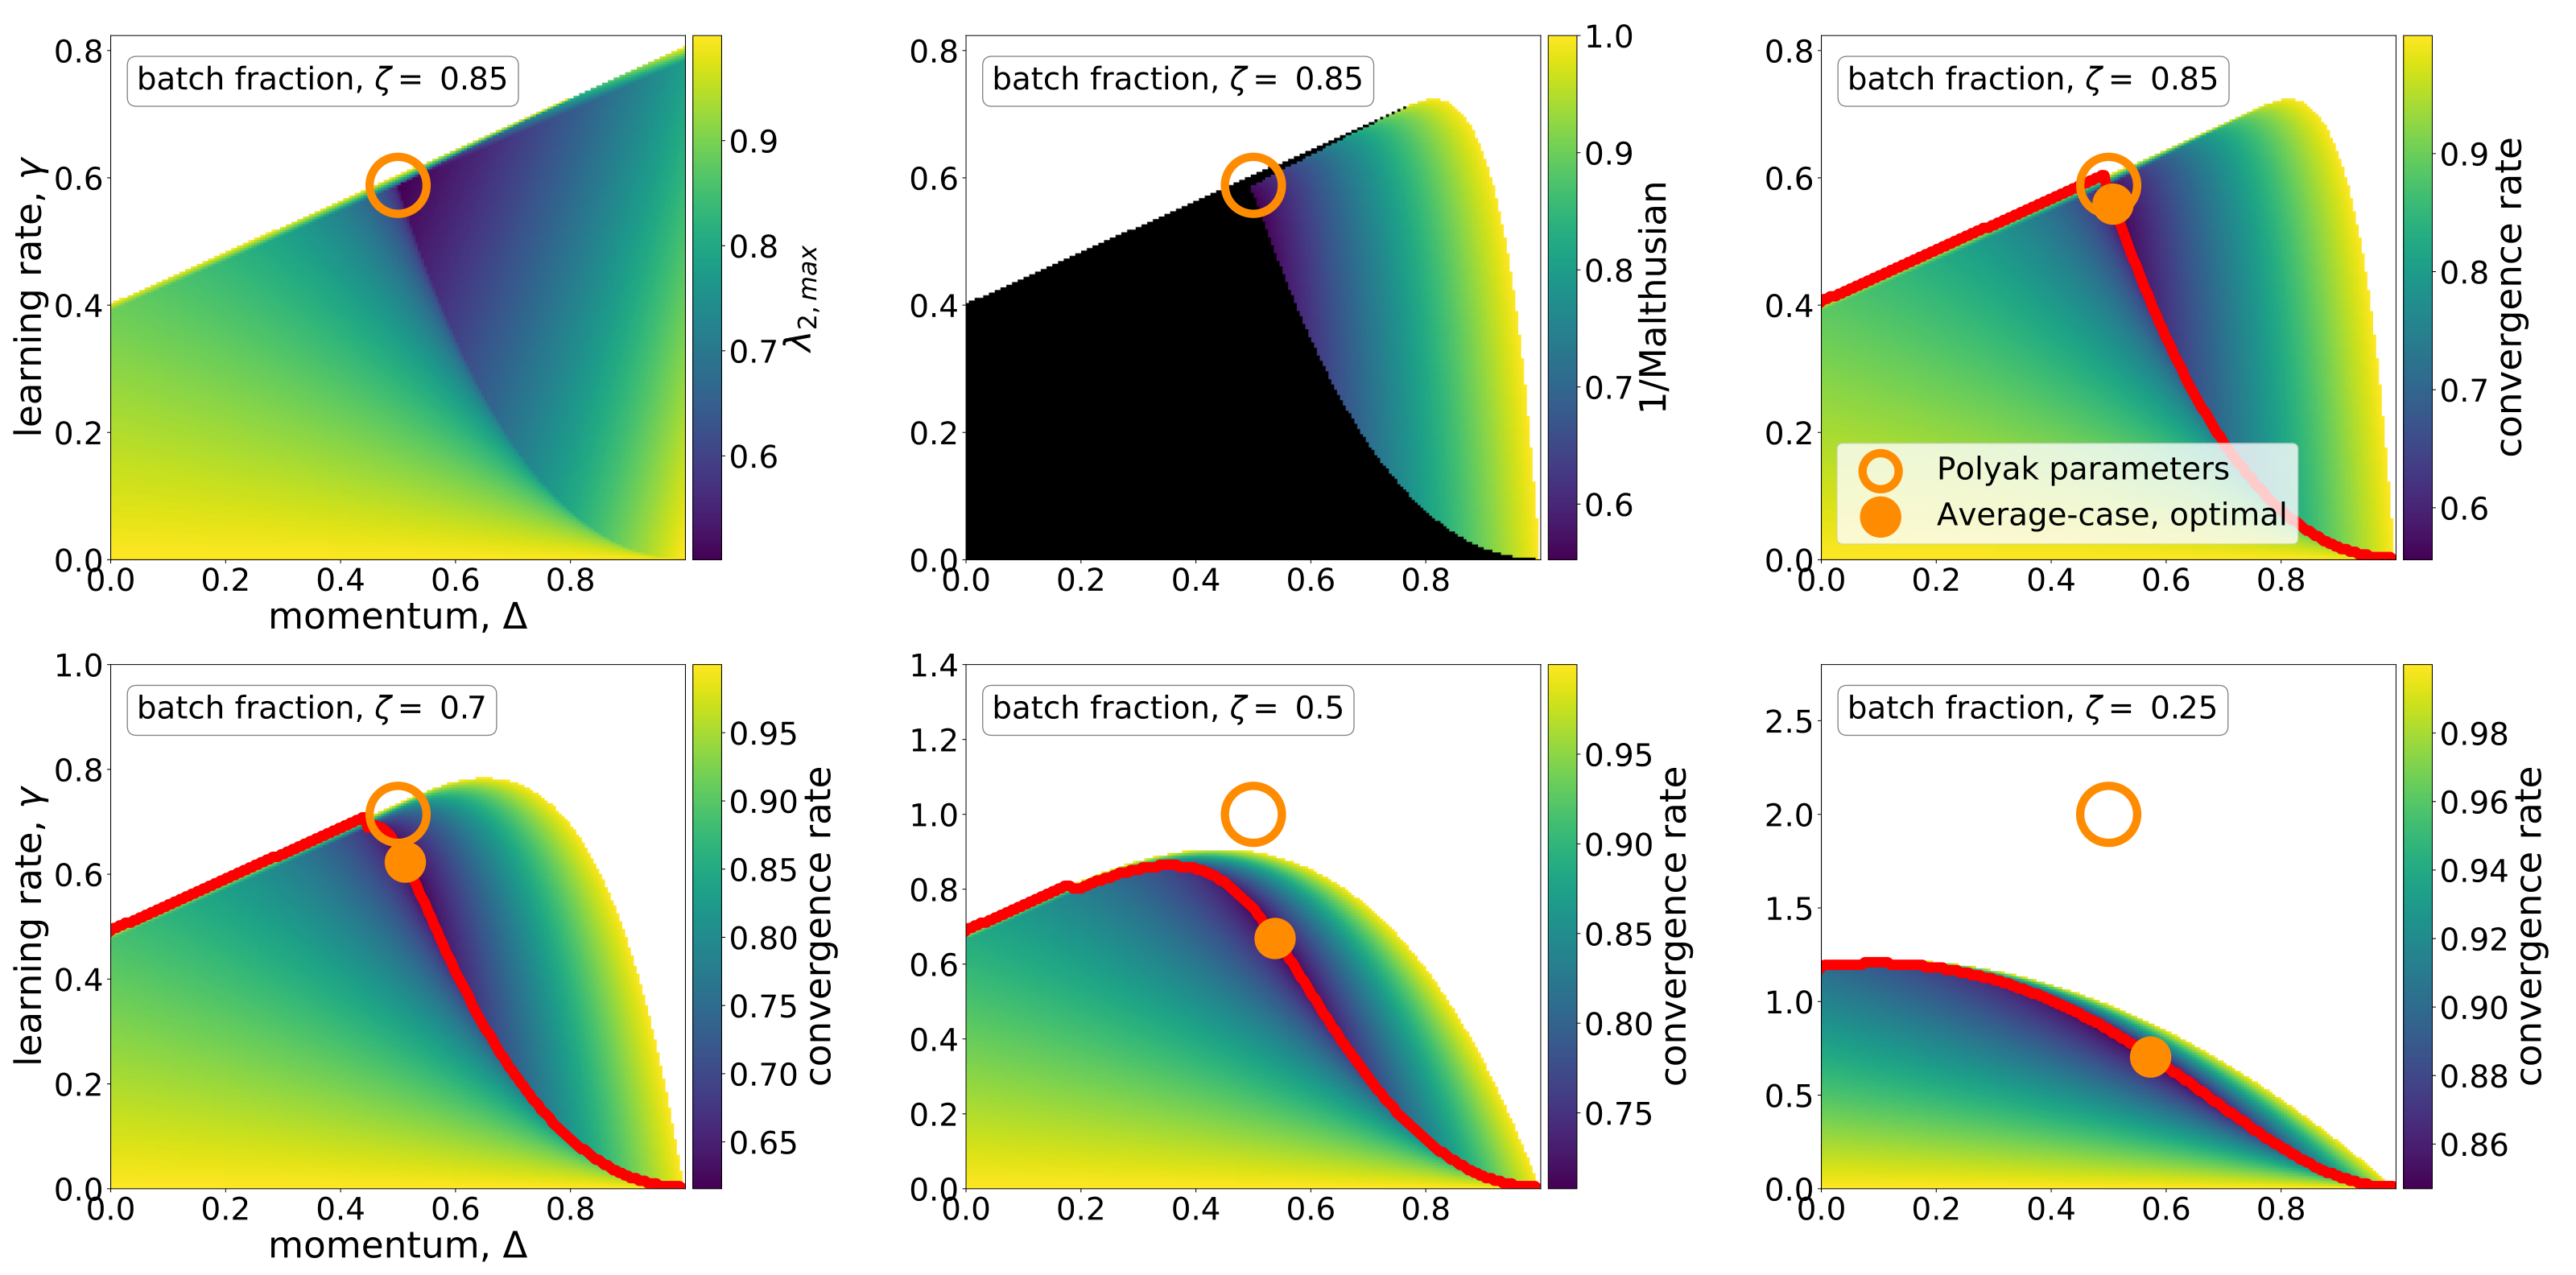
Complete original Figure 4: six heatmaps of momentum and learning rate, showing the spectral component, Malthusian component, and convergence rates at different batch fractions.

The complete Figure 4. Horizontal axes: momentum Δ; vertical axes: learning rate γ. Axis ranges and color scales differ across panels.

Polyak parameters Average-case optimum
Figure 4 · source paper

Research figure

Source paper